MODA Launches Call for Private-Sector Text Data Contributions for Sovereign AI Corpus, Inviting Writers and Publishers to Join
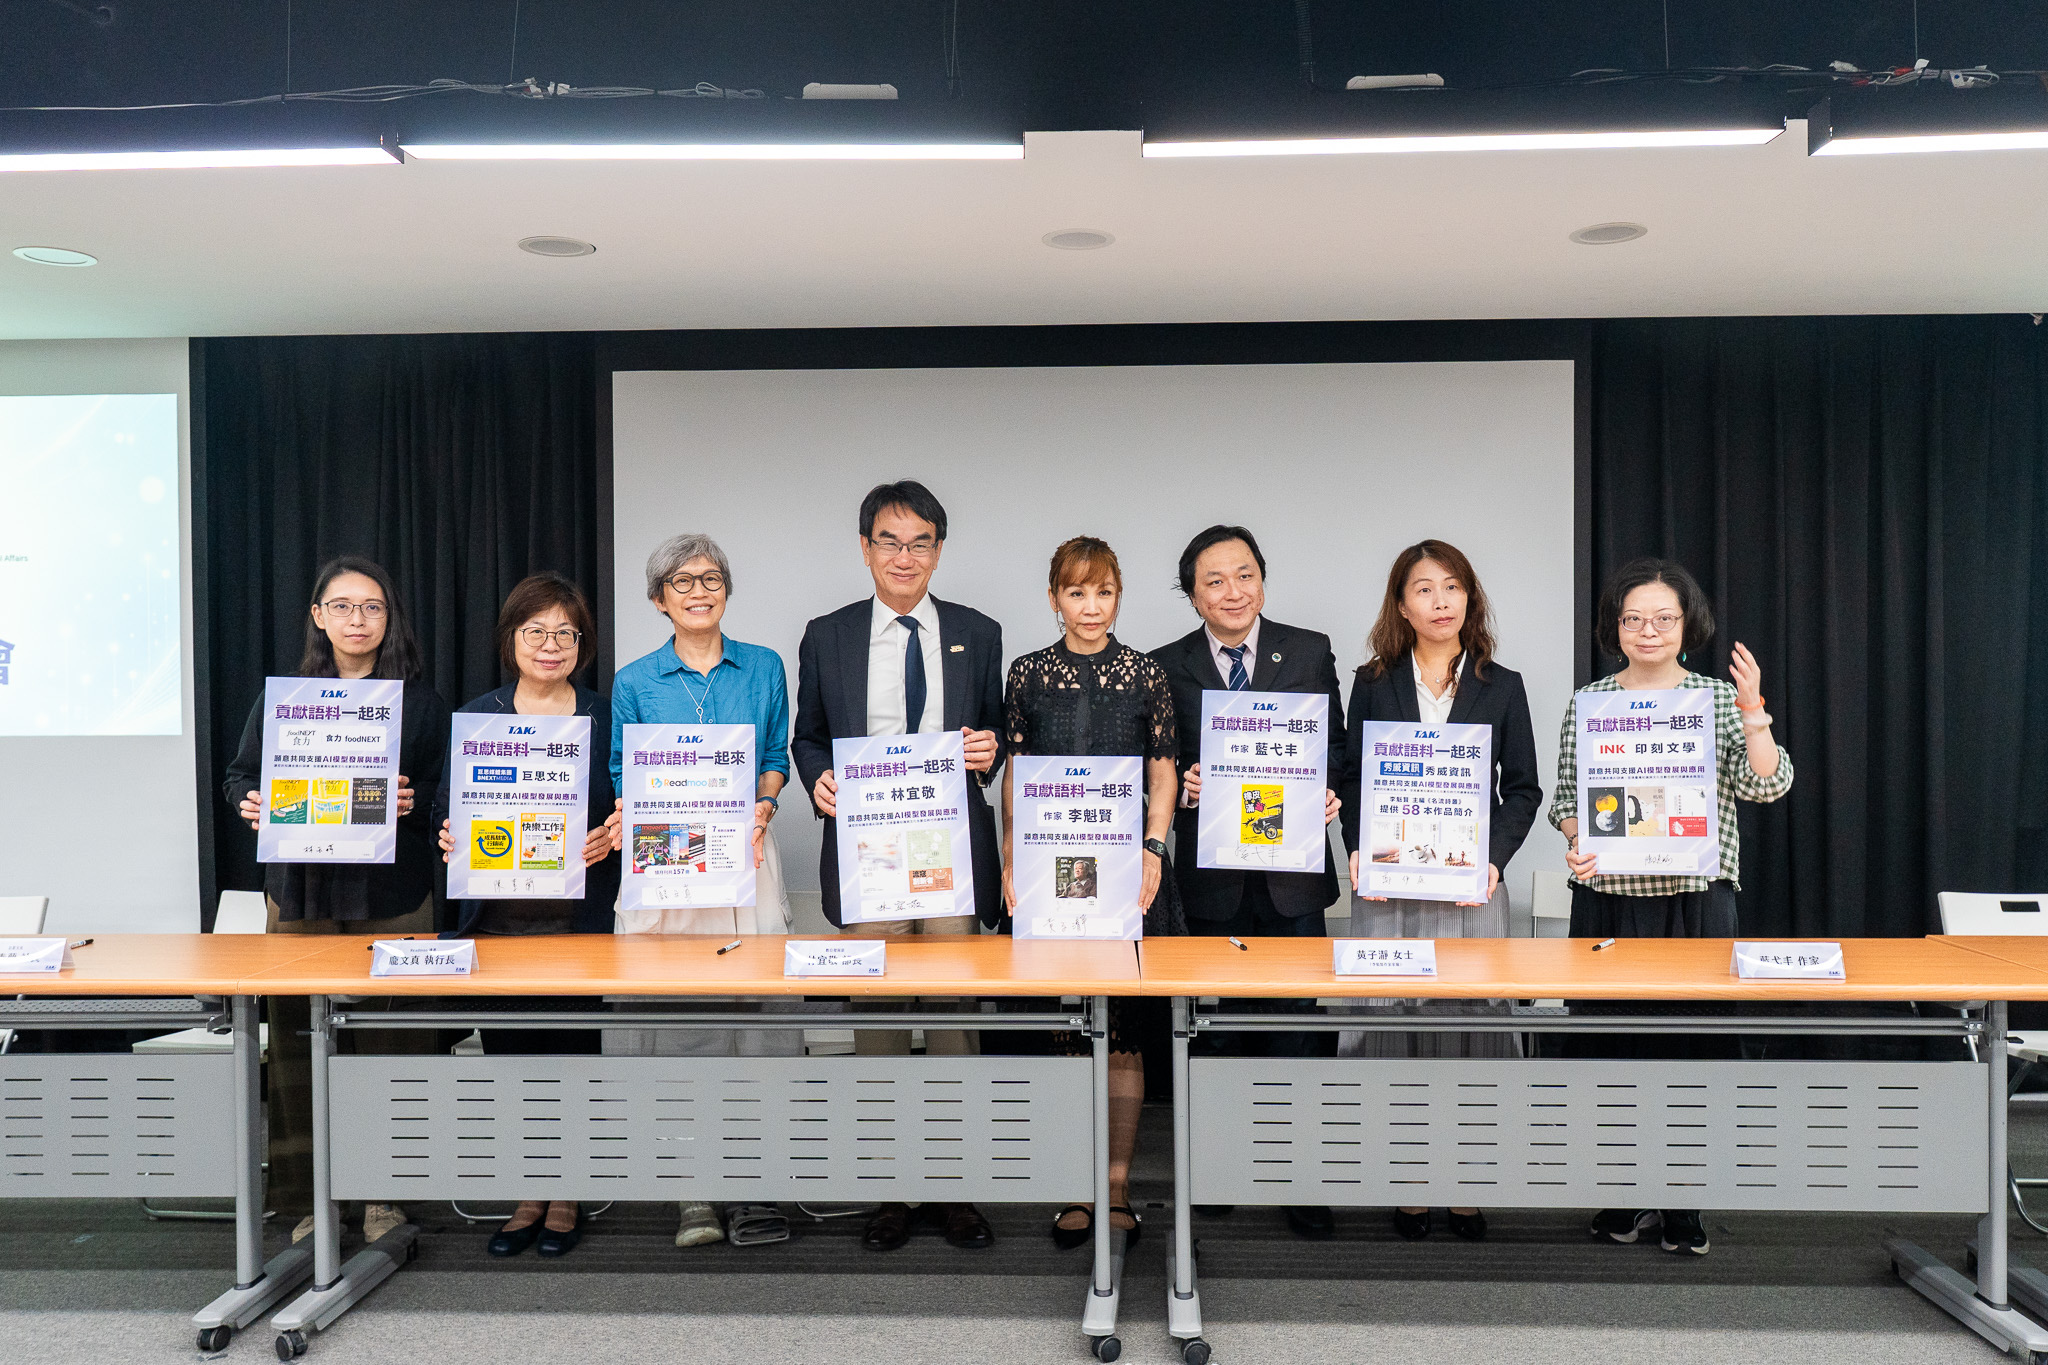
To help AI models better understand Taiwan’s language, culture, history, and social context, the Ministry of Digital Affairs (MODA) today (15th) officially launched a call for private-sector text data contributions for the “Taiwan Sovereign AI Training Corpus.” Taking the lead as an author, MODA Minister Lin Yi-jing donated his personal works The Happy Island (《幸福的鬼島》) and Roving Bandits and Innovators (《流寇與創新者》) , while joining forces with prominent writers, publishers, and e-book platforms to sign authorization agreements at the press conference, hoping to set an example that inspires broader creative private-sector participation to build trustworthy AI models with distinct Taiwanese characteristics.
At today’s press conference held by MODA to launch the call for private-sector text data contributions, publishing and e-book platform operators, including Showwe Information, ink literary, Readmoo, foodNEXT, and Business Next Media, as well as writers such as Lan Yi-feng and a family representative of Li Kuei-hsien, attended in person to sign authorization agreements. Writers such as Chen Ming-chung, Lian Ming-wei, Chu Kuo-chen, and Chu He-chih also contributed their works in response to the call.
Minister Lin pointed out that an AI model’s understanding of concepts such as democracy and checks and balances is shaped by the social and cultural contexts of its training data. Currently, Chinese-language training data in major global models remains predominantly in simplified Chinese. Therefore, to ensure AI better understands Taiwan, its language, culture, and core values must be integrated into the AI’s learning process.
MODA stated that the Taiwan Sovereign AI Training Corpus was launched late last year (2025), initially focusing on data from central and local government agencies, adding that as of late August this year, its scale had reached approximately 2.2 billion tokens. The agency added that today’s call for private-sector text data contributions represented a major milestone, signaling a new stage in the corpus’s development.
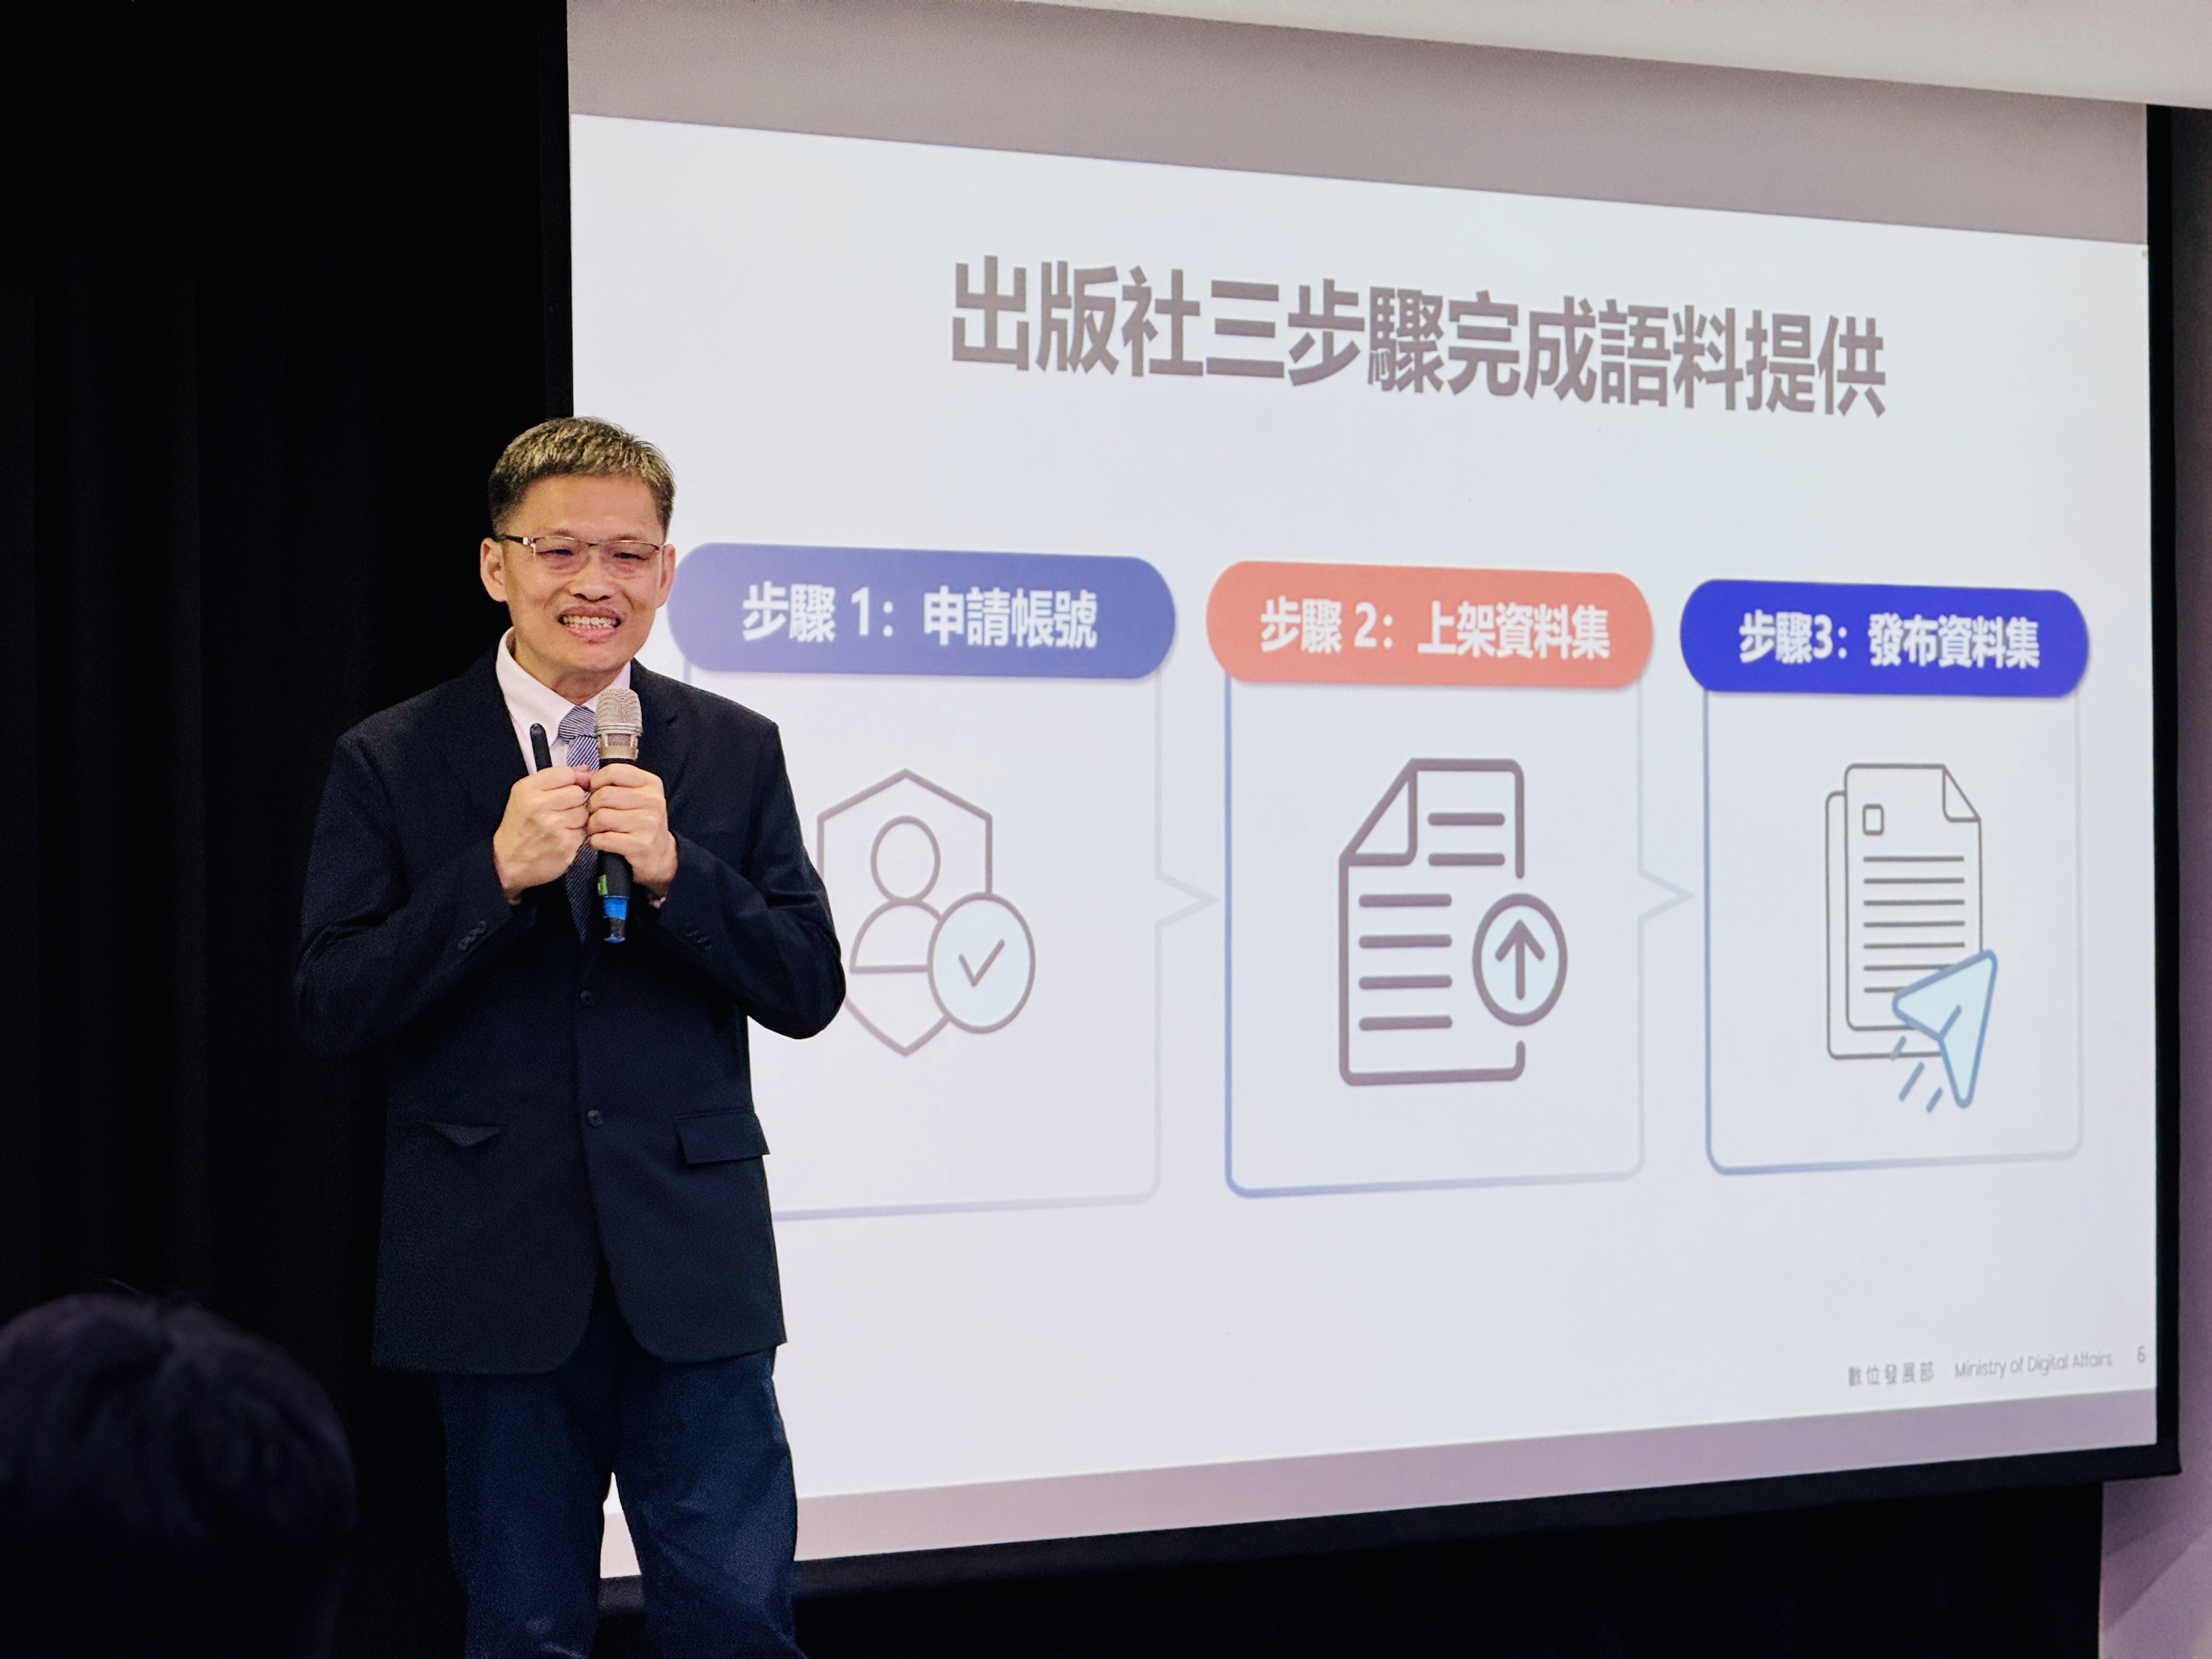
MODA explained that at this stage, the initiative is targeting publishers and e-book platforms with rich text data resources, operating on a royalty-free licensing model. Authors wishing to contribute their works can have their publishers assist in uploading them to the corpus. The primary content collected falls into four main categories: publications contributed with authorization, publication descriptions, preview excerpts, and classics and creative works whose copyright protection has expired and that can be revitalized for use as public-domain resources.
Addressing key concerns regarding copyright holders’ rights, MODA specifically emphasized that the data collection adopts three main principles: “voluntary participation, explicit authorization, optional withdrawal.” In addition to establishing a clear authorization mechanism, a comprehensive application channel for withdrawal and removal has been set up to ensure that the wishes and rights of copyright holders are fully respected while promoting AI development.
Encouraging interested parties to take immediate action, MODA sincerely invites authors, publishers, cultural institutions, corporate entities, and content providers from all fields to join. Together, we can help make more locally produced Taiwanese content a vital source of nourishment for developing Taiwan’s sovereign AI models.
Taiwan Sovereign AI Training Corpus: https://taic.moda.gov.tw/
Inquiry Hotline: 0800-023-300
Service Email: [email protected]